Inside Agentic AI Workloads
Agentic workloads repeatedly re-enter model inference over growing state. We characterize how trajectories, KV-cache retention, and tool use shape serving demand.
A blog about our lab's research on high performance AI systems.
Agentic workloads repeatedly re-enter model inference over growing state. We characterize how trajectories, KV-cache retention, and tool use shape serving demand.
Showing 3 previous posts tagged Kernel Optimization.
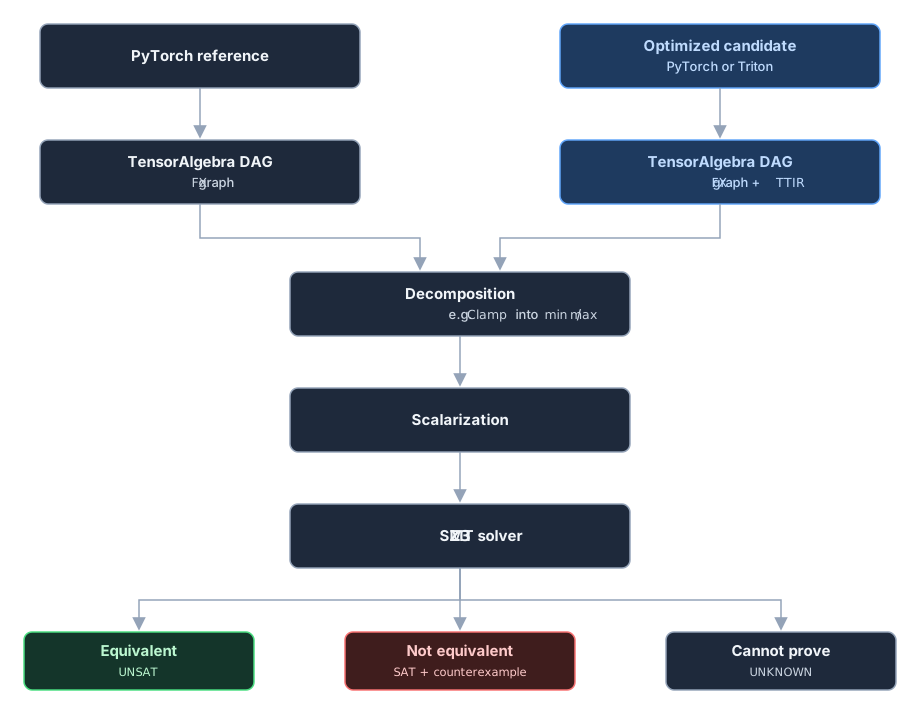
As AI agents get better at generating performant GPU kernels, building trust in their outputs becomes the bottleneck. At Gimlet, we've built an early research system that uses formal verification to complement traditional numeric tests in catching bugs in AI-generated kernels.
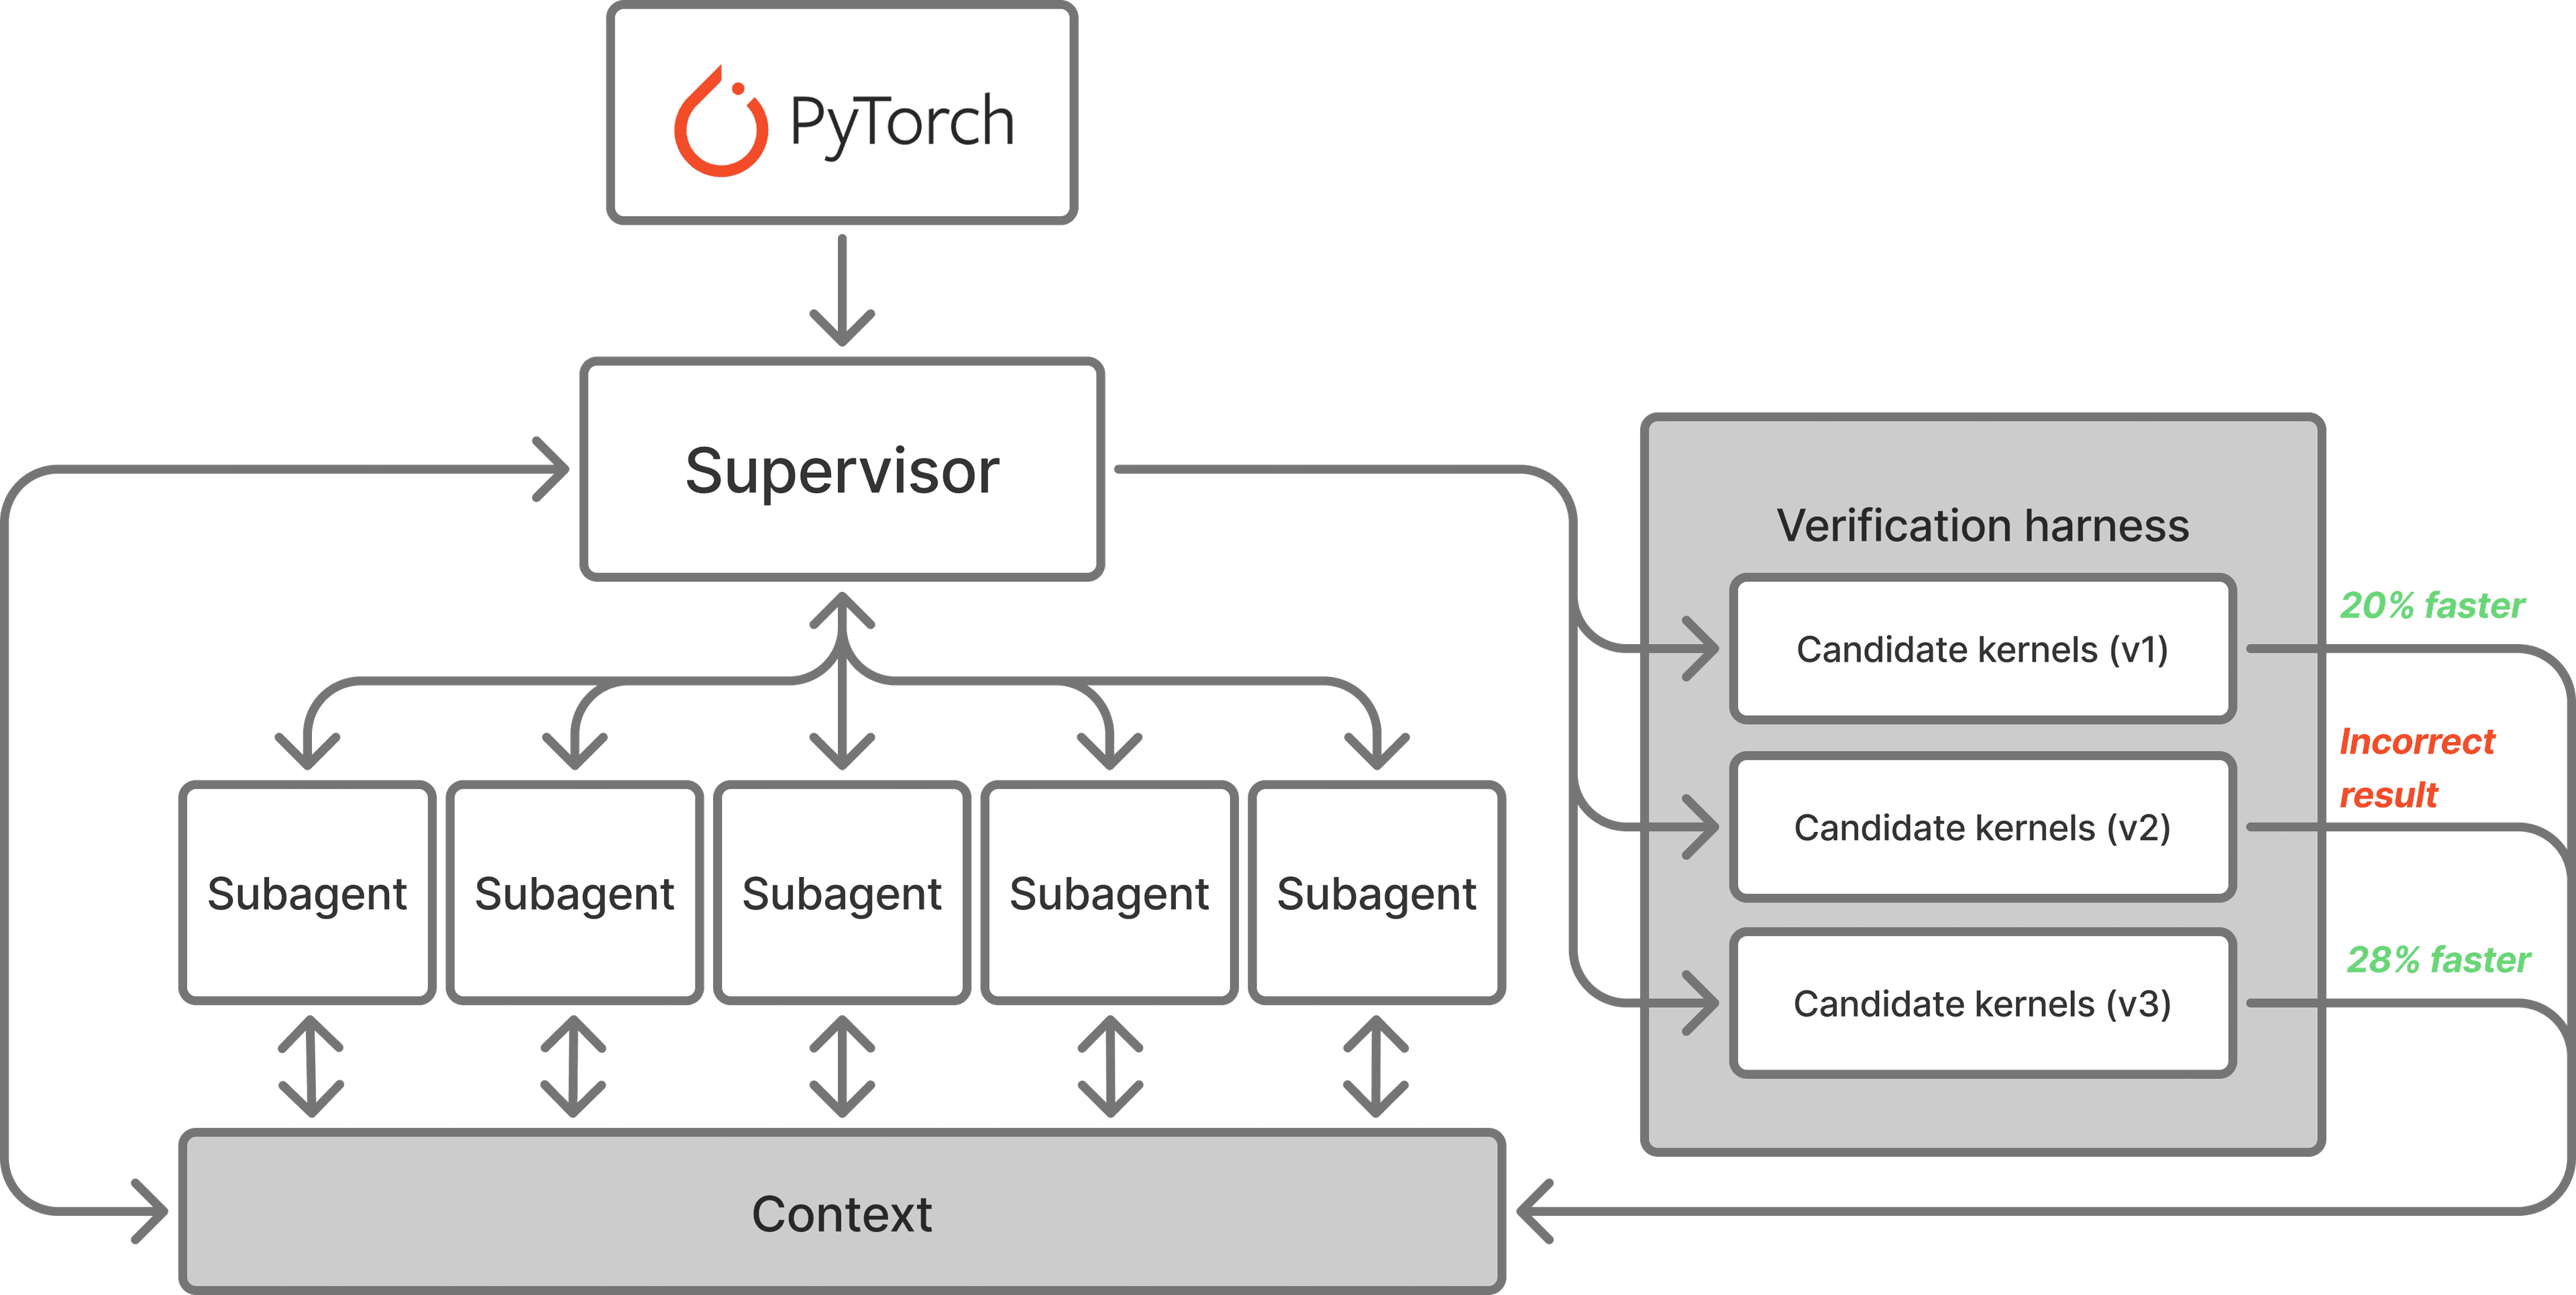
We extended our kernel generation research to CUDA, benchmarking on an H100 where generated kernels achieve around 1.8X speedups over baseline PyTorch (including torch.compile).
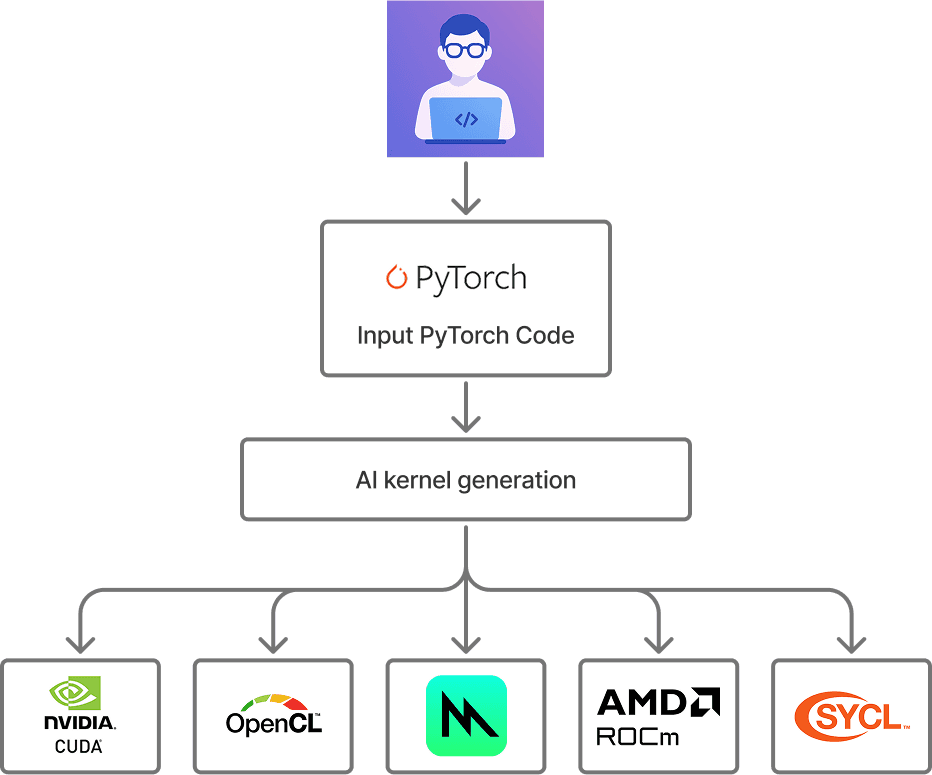
Our lab investigated whether frontier models can write optimized GPU kernels for Apple devices to speed up inference. We found that they can: our AI-generated Metal kernels were 1.24x faster across KernelBench v0.1 problems, and 1.87x faster across KernelBench v0 problems.