Inside Agentic AI Workloads
Agentic workloads repeatedly re-enter model inference over growing state. We characterize how trajectories, KV-cache retention, and tool use shape serving demand.
A blog about our lab's research on high performance AI systems.
Agentic workloads repeatedly re-enter model inference over growing state. We characterize how trajectories, KV-cache retention, and tool use shape serving demand.
Showing 2 previous posts tagged Efficiency.
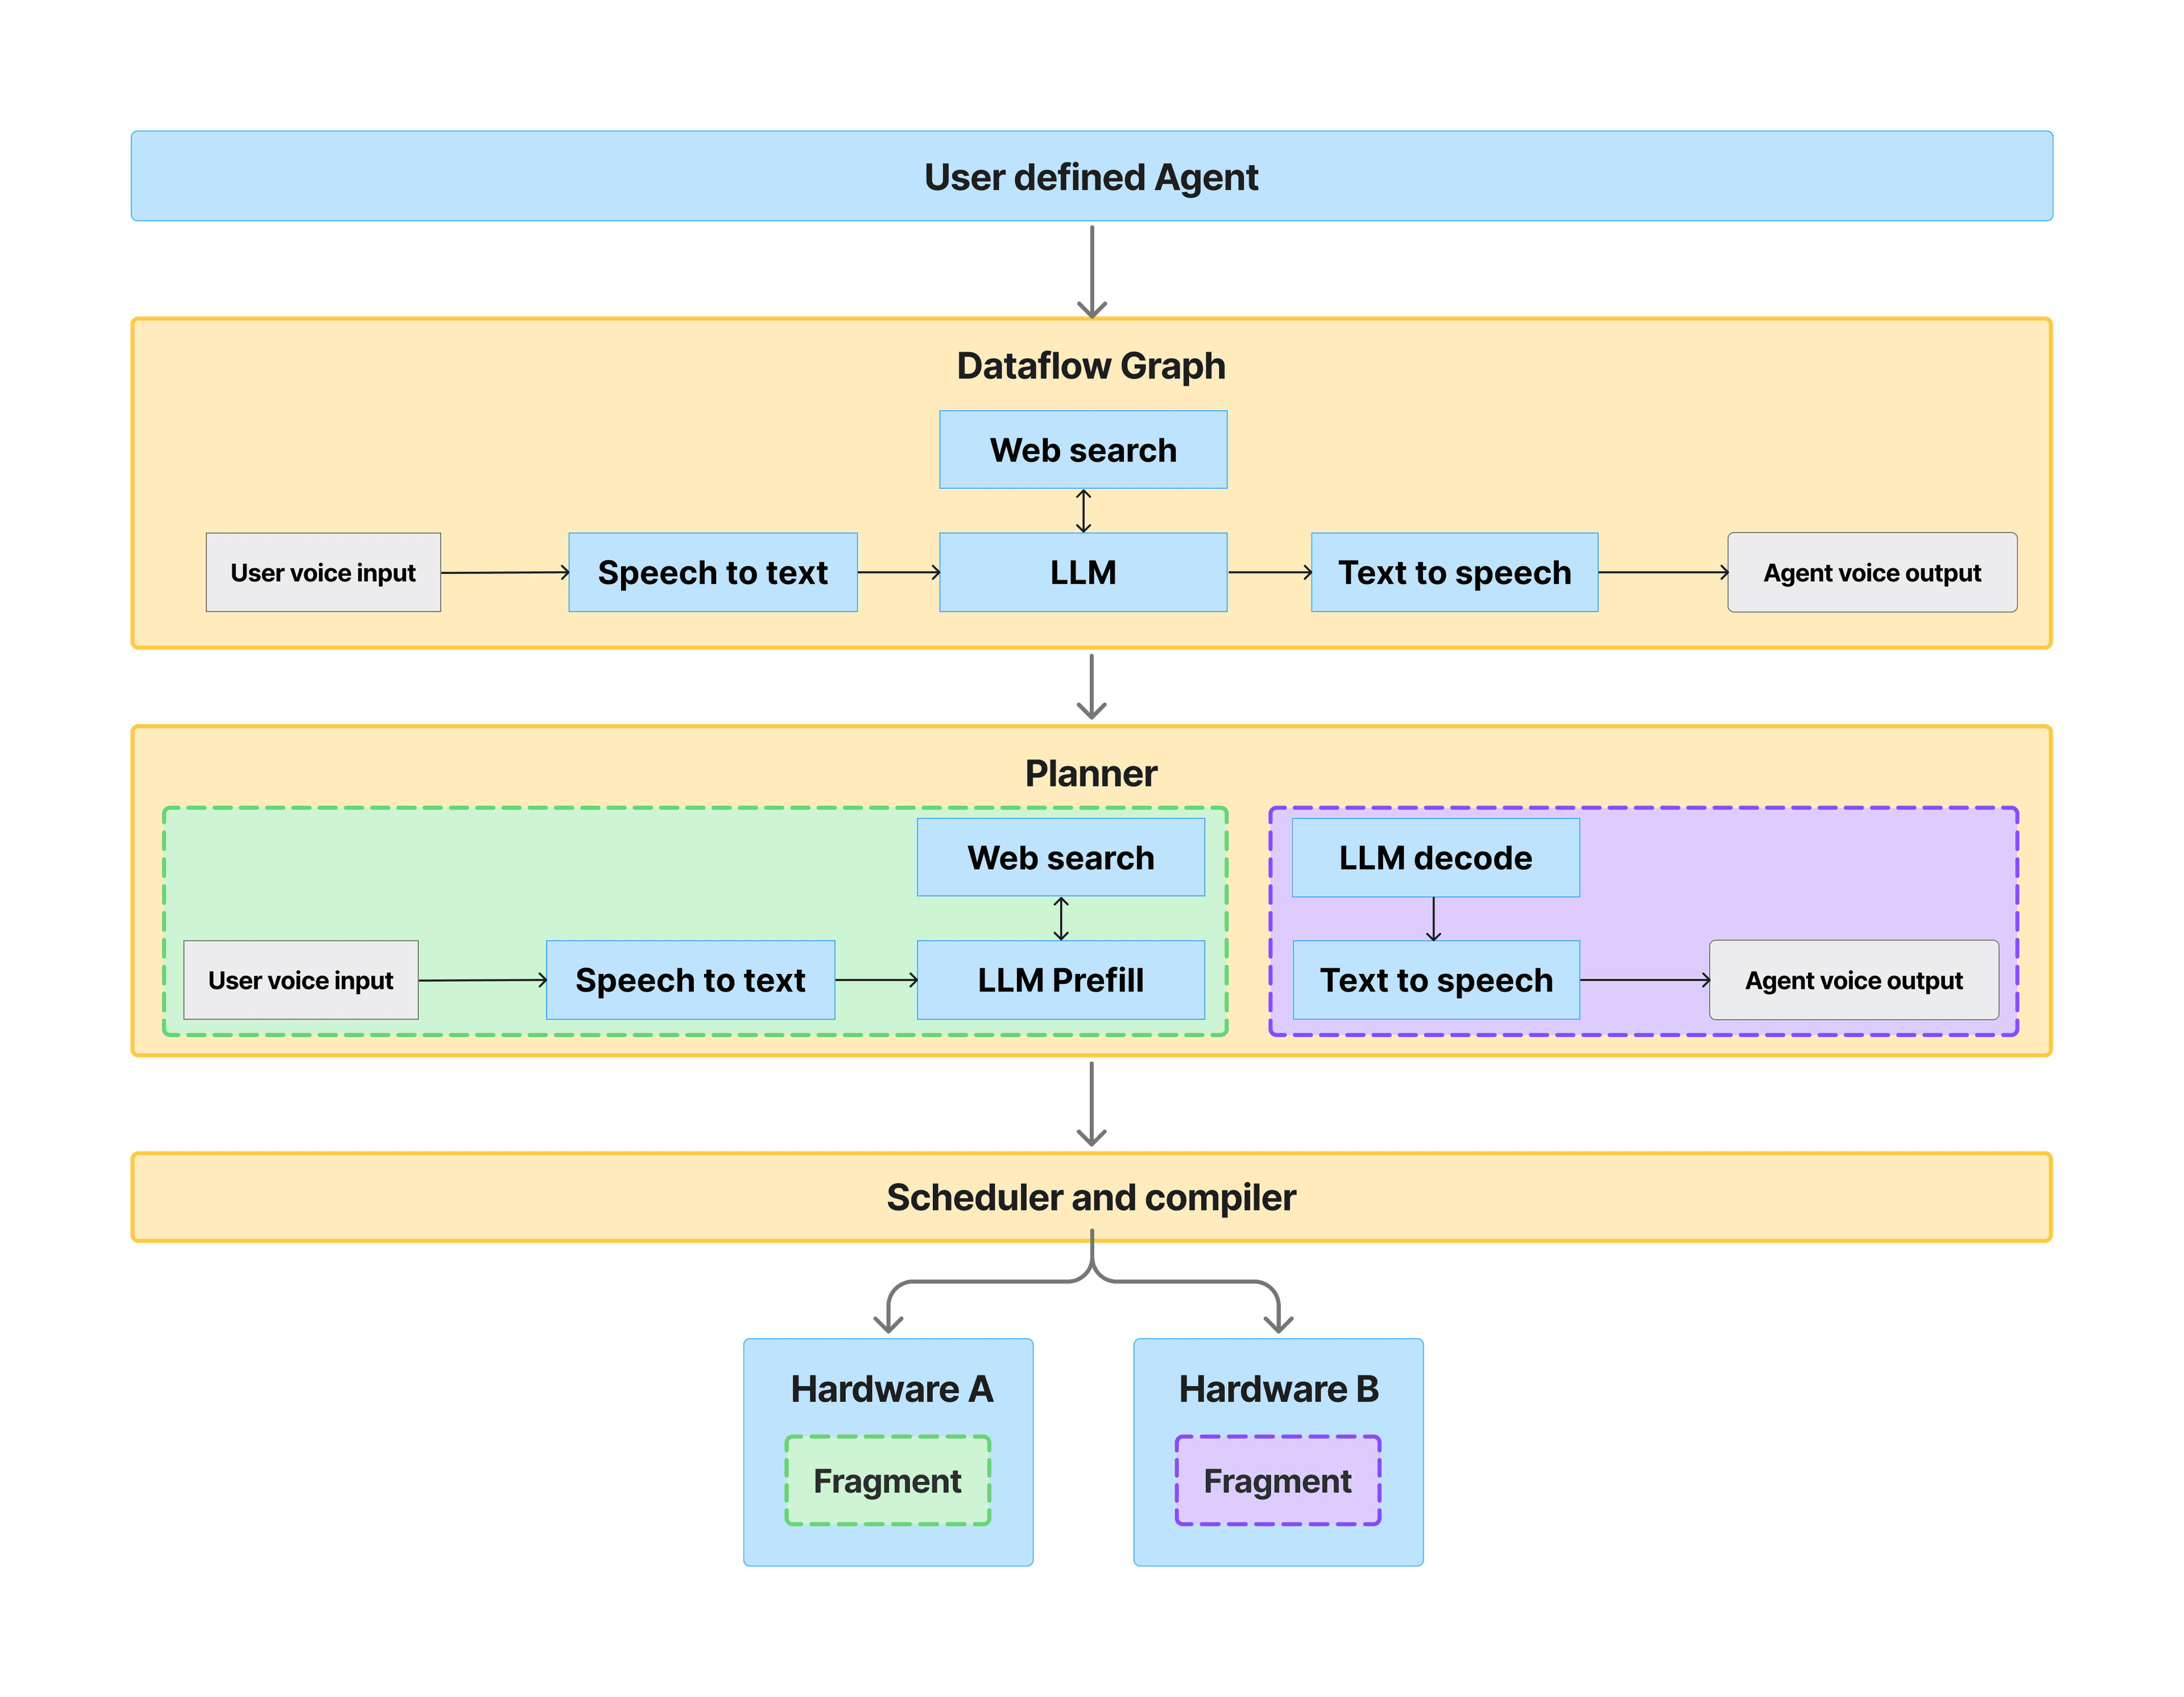
AI workloads are shifting from simple LLM inference to complex, multi-model workflows. To run them efficiently at scale, we need a system that can dynamically decompose workloads, plan and schedule them, and map execution to the right hardware.
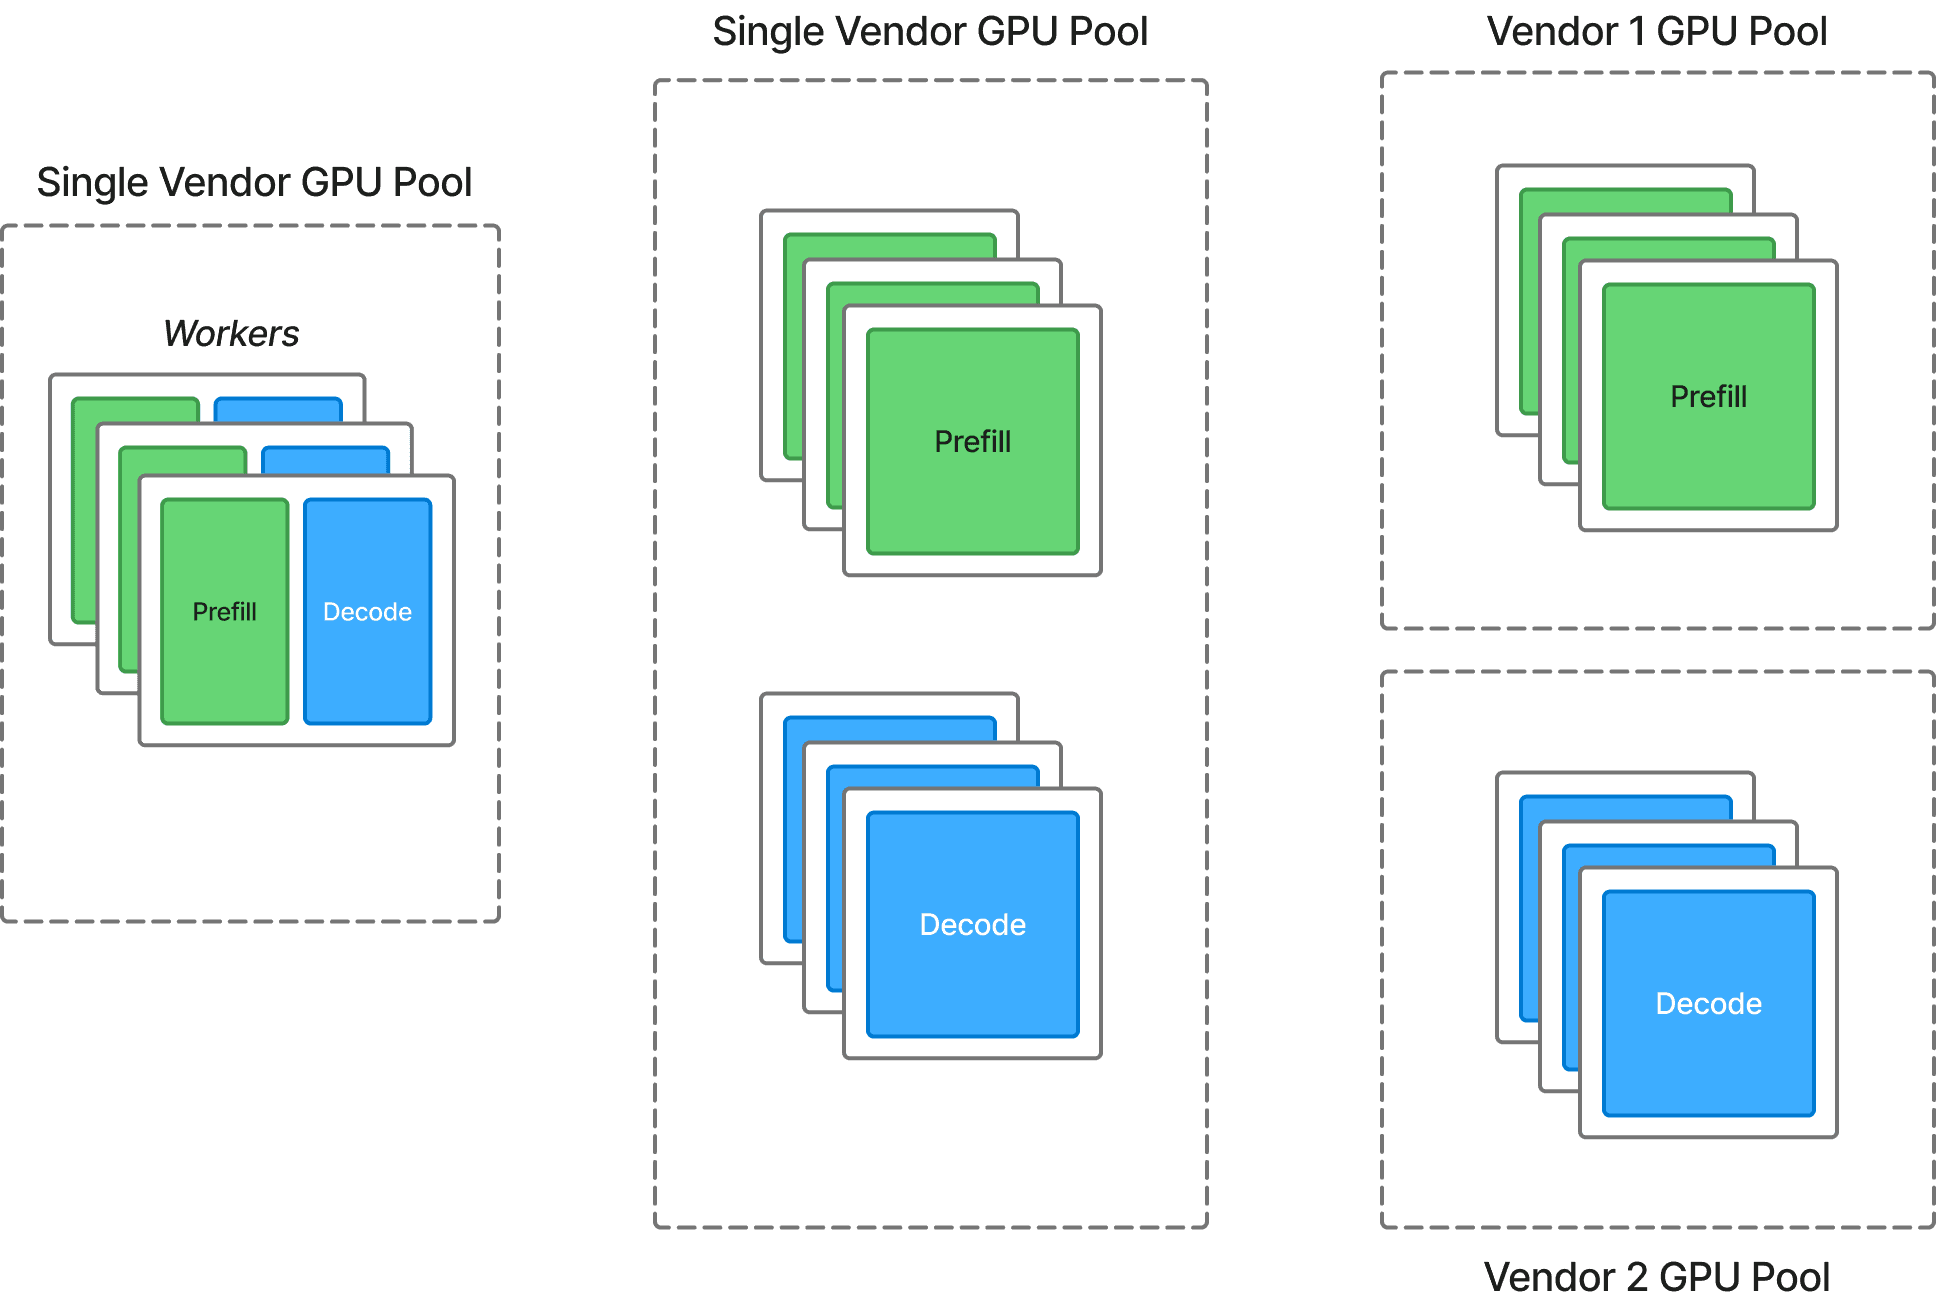
Separating prefill and decode stages of LLM inference improves token throughput because their resource needs differ. Although most deployments use NVIDIA hardware for both stages, multivendor disaggregation can actually improve efficiency while maintaining SLAs. Based on our models using NVIDIA B200s and Intel Gaudi 3, common workloads can see 1.7X TCO improvement compared to single-vendor disaggregation.